MONITORING AND OBSERVABILITY
(IT MONITORING & OBSERVABILITY)
Continuously monitor networks, servers, applications, and cloud services from one console. Combine metrics, logs, and traces into a unified view to spot anomalies before they affect the business.
IT MONITORING AND OBSERVABILITY
Continuously monitor networks, servers, applications, and cloud services from one console. Combine metrics, logs, and traces into a unified view to spot anomalies before they affect the business.
Key benefits
Monitoring and observability bring network, server, application, and cloud data into one system to detect anomalies early, identify root causes faster, and support informed infrastructure decisions.

A unified infrastructure view
End-to-end visibility from network ports to business applications.

Processes aligned with international standards
Monitoring and event management follow ITIL 4 practices and ISO/IEC 20000-1:2018 requirements.

Predictive failure detection
AI-powered analytics (AIOps) detects anomalies early and identifies likely root causes.

Less downtime and lower MTTR
Event correlation and incident prioritization shorten IT response times.

Distributed site monitoring.
Monitor offices, branches, and production sites centrally without engineer visits.

Business visibility
Service availability dashboards support management decisions on capacity and budgets.
Key benefits
Monitoring and observability bring network, server, application, and cloud data into one system to detect anomalies early, identify root causes faster, and support informed infrastructure decisions.
A unified infrastructure view
End-to-end visibility from network ports to business applications.
Processes aligned with international standards
Monitoring and event management follow ITIL 4 practices and ISO/IEC 20000-1:2018 requirements.
Predictive failure detection
AI-powered analytics (AIOps) detects anomalies early and identifies likely root causes.
Less downtime and lower MTTR
Event correlation and incident prioritization shorten IT response times.
Distributed site monitoring.
Monitor offices, branches, and production sites centrally without engineer visits.
Business visibility
Service availability dashboards support management decisions on capacity and budgets.
Key features
The solution scales to infrastructure of any size, from one office to distributed sites with hybrid and cloud services. Features are selected to match your architecture and IT process maturity.
Key features
The solution scales to infrastructure of any size, from one office to distributed sites with hybrid and cloud services. Features are selected to match your architecture and IT process maturity.
Unified visibility across all components
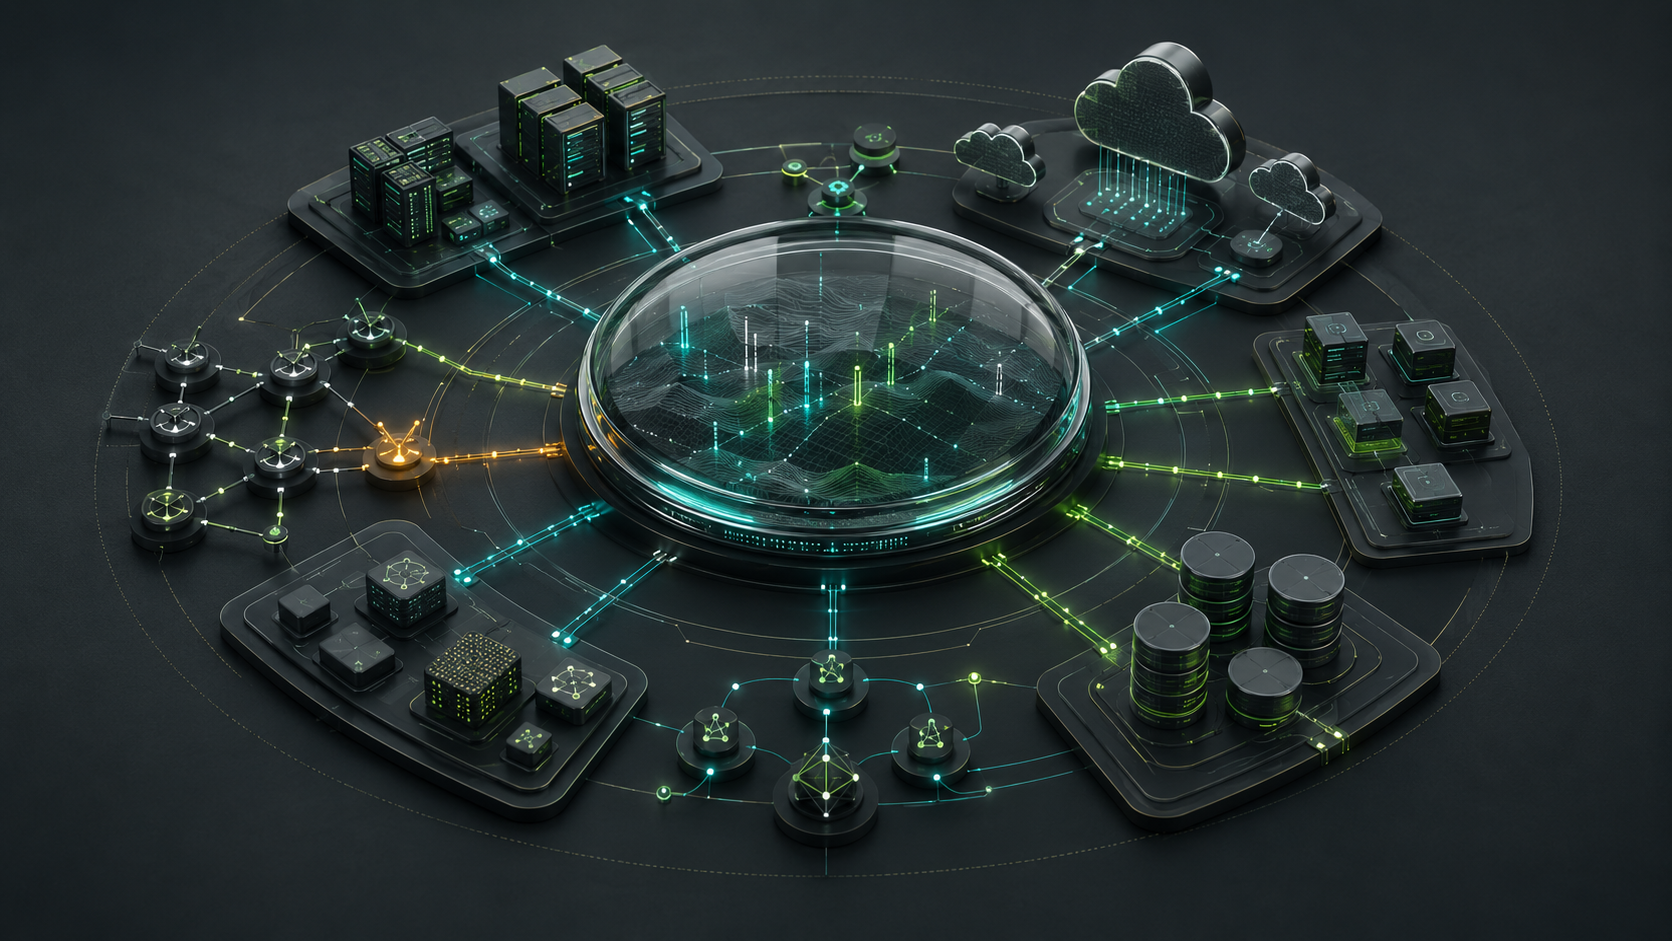
We bring network, server, application, and cloud data into one monitoring environment. Expand the sections below to see which metrics and events the system tracks.
- Network monitoring: Availability and performance of equipment, connectivity, Wi-Fi, and branch connections.
- Application and server monitoring (APM): Response times, resource consumption, and virtual machine health.
- Logs, metrics, and traces: centralized telemetry and root cause analysis across the service chain.
- Infrastructure health dashboards: Dashboards for IT teams and management, including large-screen displays for control rooms.
- Capacity planning: Analyze workload trends to expand resources at the right time.
Unified visibility across all components
We bring network, server, application, and cloud data into one monitoring environment. Expand the sections below to see which metrics and events the system tracks.
- Network monitoring: Availability and performance of equipment, connectivity, Wi-Fi, and branch connections.
- Application and server monitoring (APM): Response times, resource consumption, and virtual machine health.
- Logs, metrics, and traces: centralized telemetry and root cause analysis across the service chain.
- Infrastructure health dashboards: Dashboards for IT teams and management, including large-screen displays for control rooms.
- Capacity planning: Analyze workload trends to expand resources at the right time.
From monitoring to observability
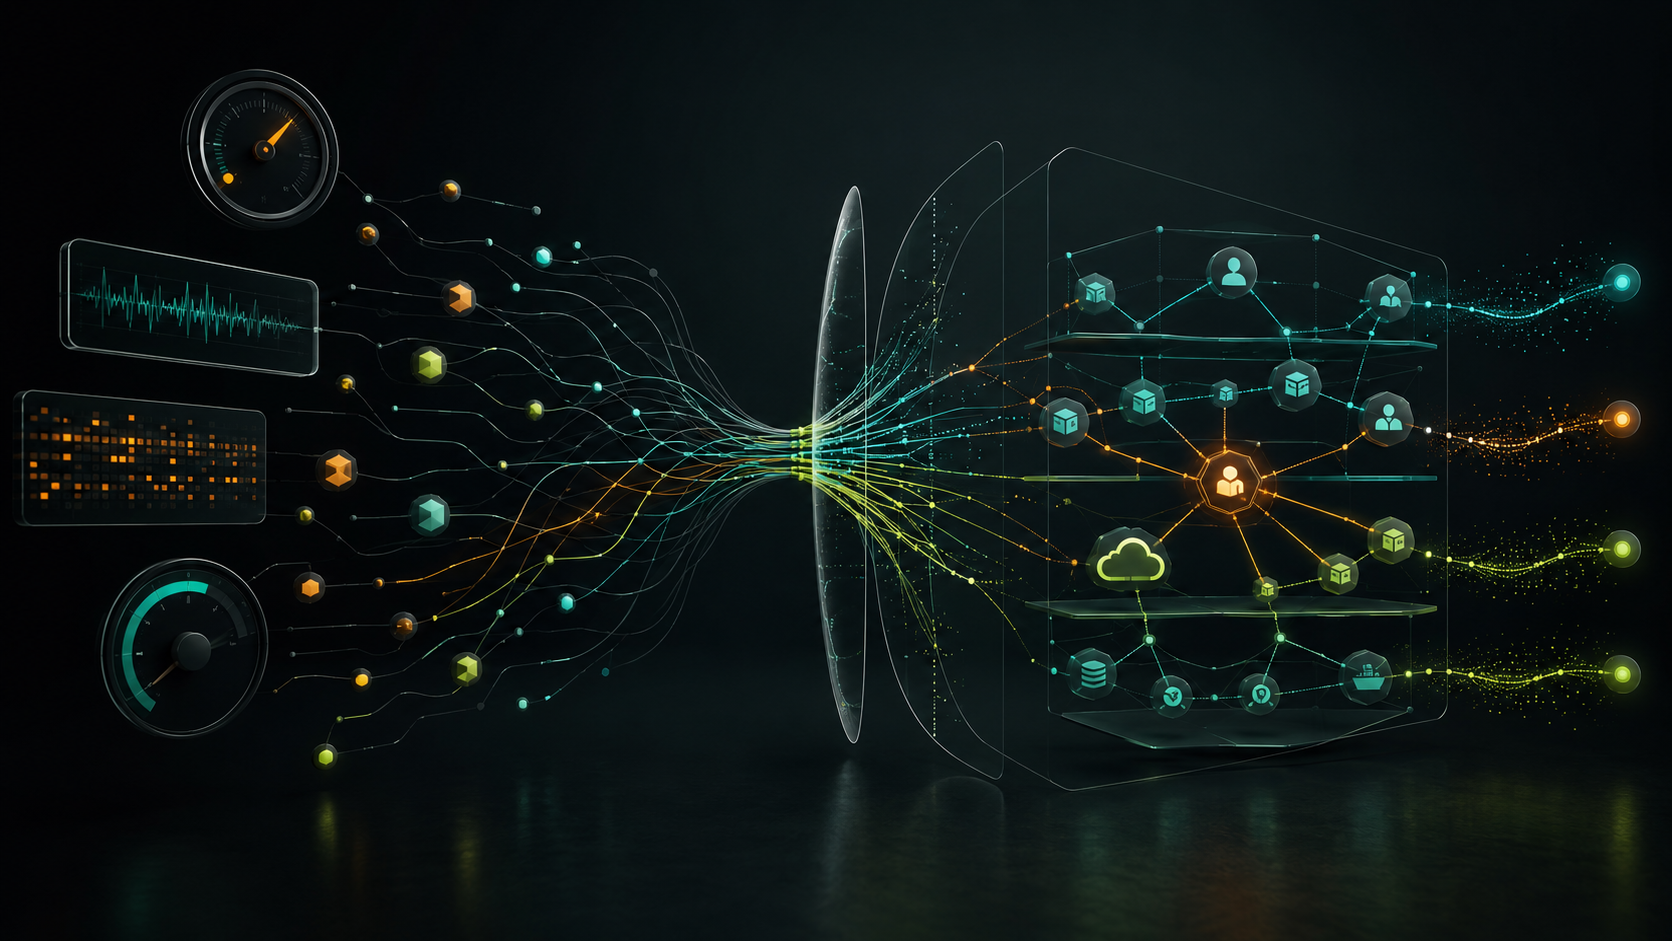
Traditional monitoring shows what happened. Observability combines data from every infrastructure component to explain why a problem occurred and how it affects business services.
- End-to-end telemetry: Logs, metrics, and traces are collected in one system, from network equipment to applications and cloud services.
- Event correlation: related events are combined into one incident so IT teams can see the root cause rather than a stream of disconnected alerts.
- SLA monitoring: dashboards show the availability and performance of key services, helping track agreed service levels.
From monitoring to observability
Traditional monitoring shows what happened. Observability combines data from every infrastructure component to explain why a problem occurred and how it affects business services.
- End-to-end telemetry: logs, metrics, and traces are collected in one system, from network equipment to applications and cloud services.
- Event correlation: related events are combined into one incident so IT teams can see the root cause rather than a stream of disconnected alerts.
- SLA monitoring: dashboards show the availability and performance of key services, helping track agreed service levels.
AIOps and automated response
AIOps analyzes infrastructure behavior, identifies the signals that matter, and helps IT teams respond faster to anomalies and common failures.
- Anomaly detection: the system learns normal component behavior and detects unusual changes before widespread errors occur.
- Duplicate alert suppression: repeated and related signals are grouped to reduce noise and the burden on specialists.
- Response playbooks: predefined actions run automatically for common failures, including diagnostics, notifying the right specialists, and incident escalation.
AIOps and automated response
AIOps analyzes infrastructure behavior, identifies the signals that matter, and helps IT teams respond faster to anomalies and common failures.
- Anomaly detection: the system learns normal component behavior and detects unusual changes before widespread errors occur.
- Duplicate alert suppression: repeated and related signals are grouped to reduce noise and the burden on specialists.
- Response playbooks: predefined actions run automatically for common failures, including diagnostics, notifying the right specialists, and incident escalation.
Monitoring as part of your IT processes
We implement monitoring as a managed process that goes beyond license delivery. We design telemetry collection, configure thresholds around business service criticality, train the IT team, and support the solution after launch.
Telemetry design
We identify sources and design a unified approach to collecting metrics, logs, and events.
Configuration aligned with business services
We define thresholds, correlation rules, and alerts around each service's criticality.
IT team training
We transfer the knowledge specialists need for daily operations, event analysis, and reporting.
Support and development
We help update configuration, add components, and develop the system as infrastructure grows.
Monitoring as part of your IT processes
We implement monitoring as a managed process that goes beyond license delivery. We design telemetry collection, configure thresholds around business service criticality, train the IT team, and support the solution after launch.
Telemetry design
We identify sources and design a unified approach to collecting metrics, logs, and events.
Configuration aligned with business services
We define thresholds, correlation rules, and alerts around each service's criticality.
IT team training
We transfer the knowledge specialists need for daily operations, event analysis, and reporting.
Support and development
We help update configuration, add components, and develop the system as infrastructure grows.
Technology partners
We use solutions from leading technology partners, selecting platforms to match the architecture, scale, and needs of each infrastructure.
Technology partners
We use solutions from leading technology partners, selecting platforms to match the architecture, scale, and needs of each infrastructure.
Related services
A comprehensive approach brings monitoring, network infrastructure, process automation, and asset tracking together in a single IT management system.
IT OPERATIONS AND AUTOMATION
We automate routine IT tasks, event handling, and standard response playbooks to reduce manual work, resolve incidents faster, and improve service stability.
NETWORKS AND WIRELESS
We design and develop reliable networks for offices, branches, and production sites, with stable, manageable connections for users, devices, and business systems.
IT ASSET MANAGEMENT
We create a unified inventory of hardware, software, and licenses throughout their lifecycle, from purchasing and commissioning to maintenance and retirement.
Want to learn more about this service?
We assess current infrastructure visibility and identify systems, events, and risks that remain outside your control.
Related services
A comprehensive approach brings monitoring, network infrastructure, process automation, and asset tracking together in a single IT management system.
IT OPERATIONS AND AUTOMATION
We automate routine IT tasks, event handling, and standard response playbooks to reduce manual work, resolve incidents faster, and improve service stability.
NETWORKS AND WIRELESS
We design and develop reliable networks for offices, branches, and production sites, with stable, manageable connections for users, devices, and business systems.
IT ASSET MANAGEMENT
We create a unified inventory of hardware, software, and licenses throughout their lifecycle, from purchasing and commissioning to maintenance and retirement.
Want to learn more about this service?
We assess current infrastructure visibility and identify systems, events, and risks that remain outside your control.